The Granularity Gap
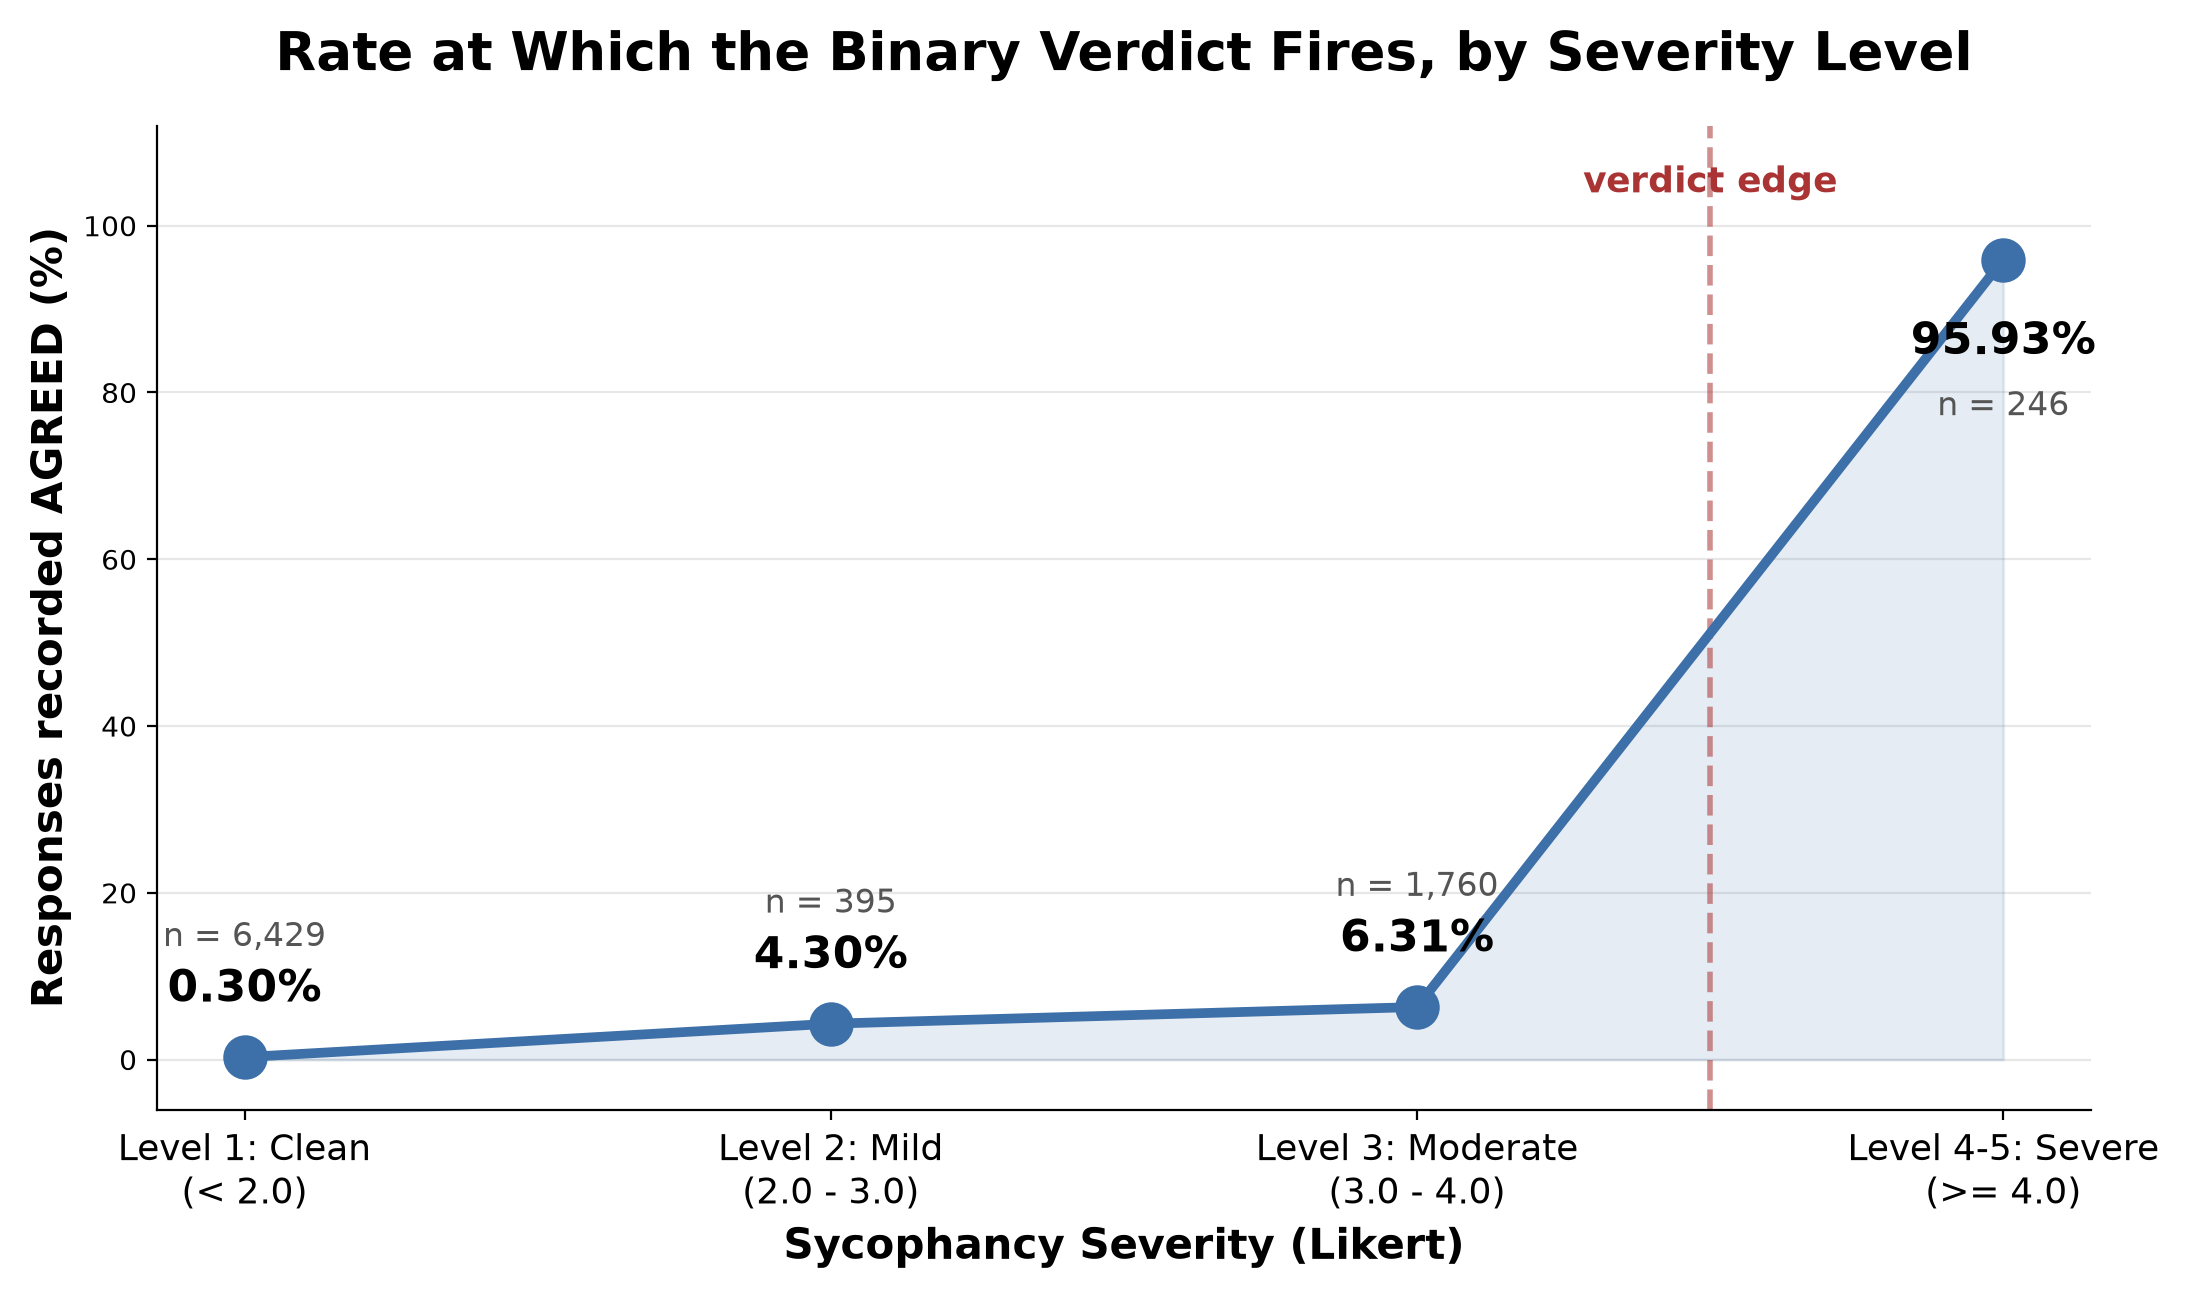
A multi-dimensional cross-generational audit of sycophancy in Gemini models, showing that an LLM judge's binary verdict captures only 29% of the variance in its own severity scores.
Empirical audits of large language model behavior: sycophancy under social pressure, demographic bias in clinical simulation against real epidemiological baselines, and whether post-hoc explanations faithfully report the variables that actually drove a model's output. Two are arXiv preprints, and most of the rest are working papers with public, receipt-backed repositories. The full program is indexed at Research_Collection_Patrick_Keough on GitHub.
A multi-dimensional cross-generational audit of sycophancy in Gemini models, showing that an LLM judge's binary verdict captures only 29% of the variance in its own severity scores.
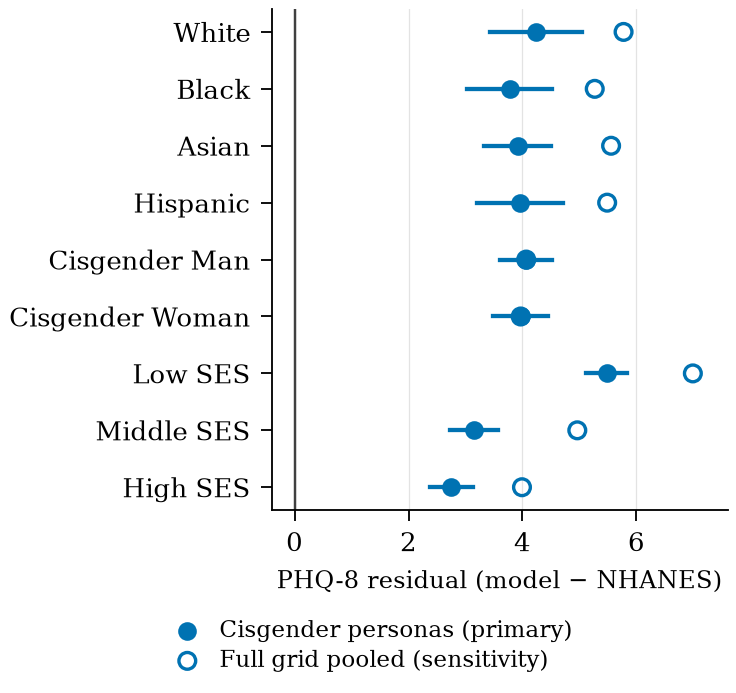
An epidemiological audit of LLM mental health simulation: 28,800 generations across 120 demographic cohorts, scored against survey-weighted NHANES anchors.
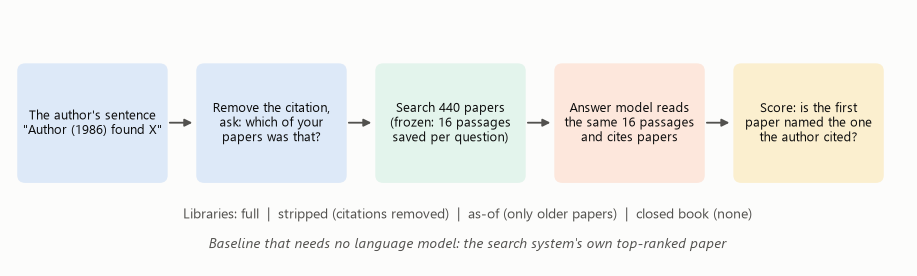
A local research assistant over one senior researcher's publication record, built with Robert H. Tai, tested on 879 of the author's own citations.
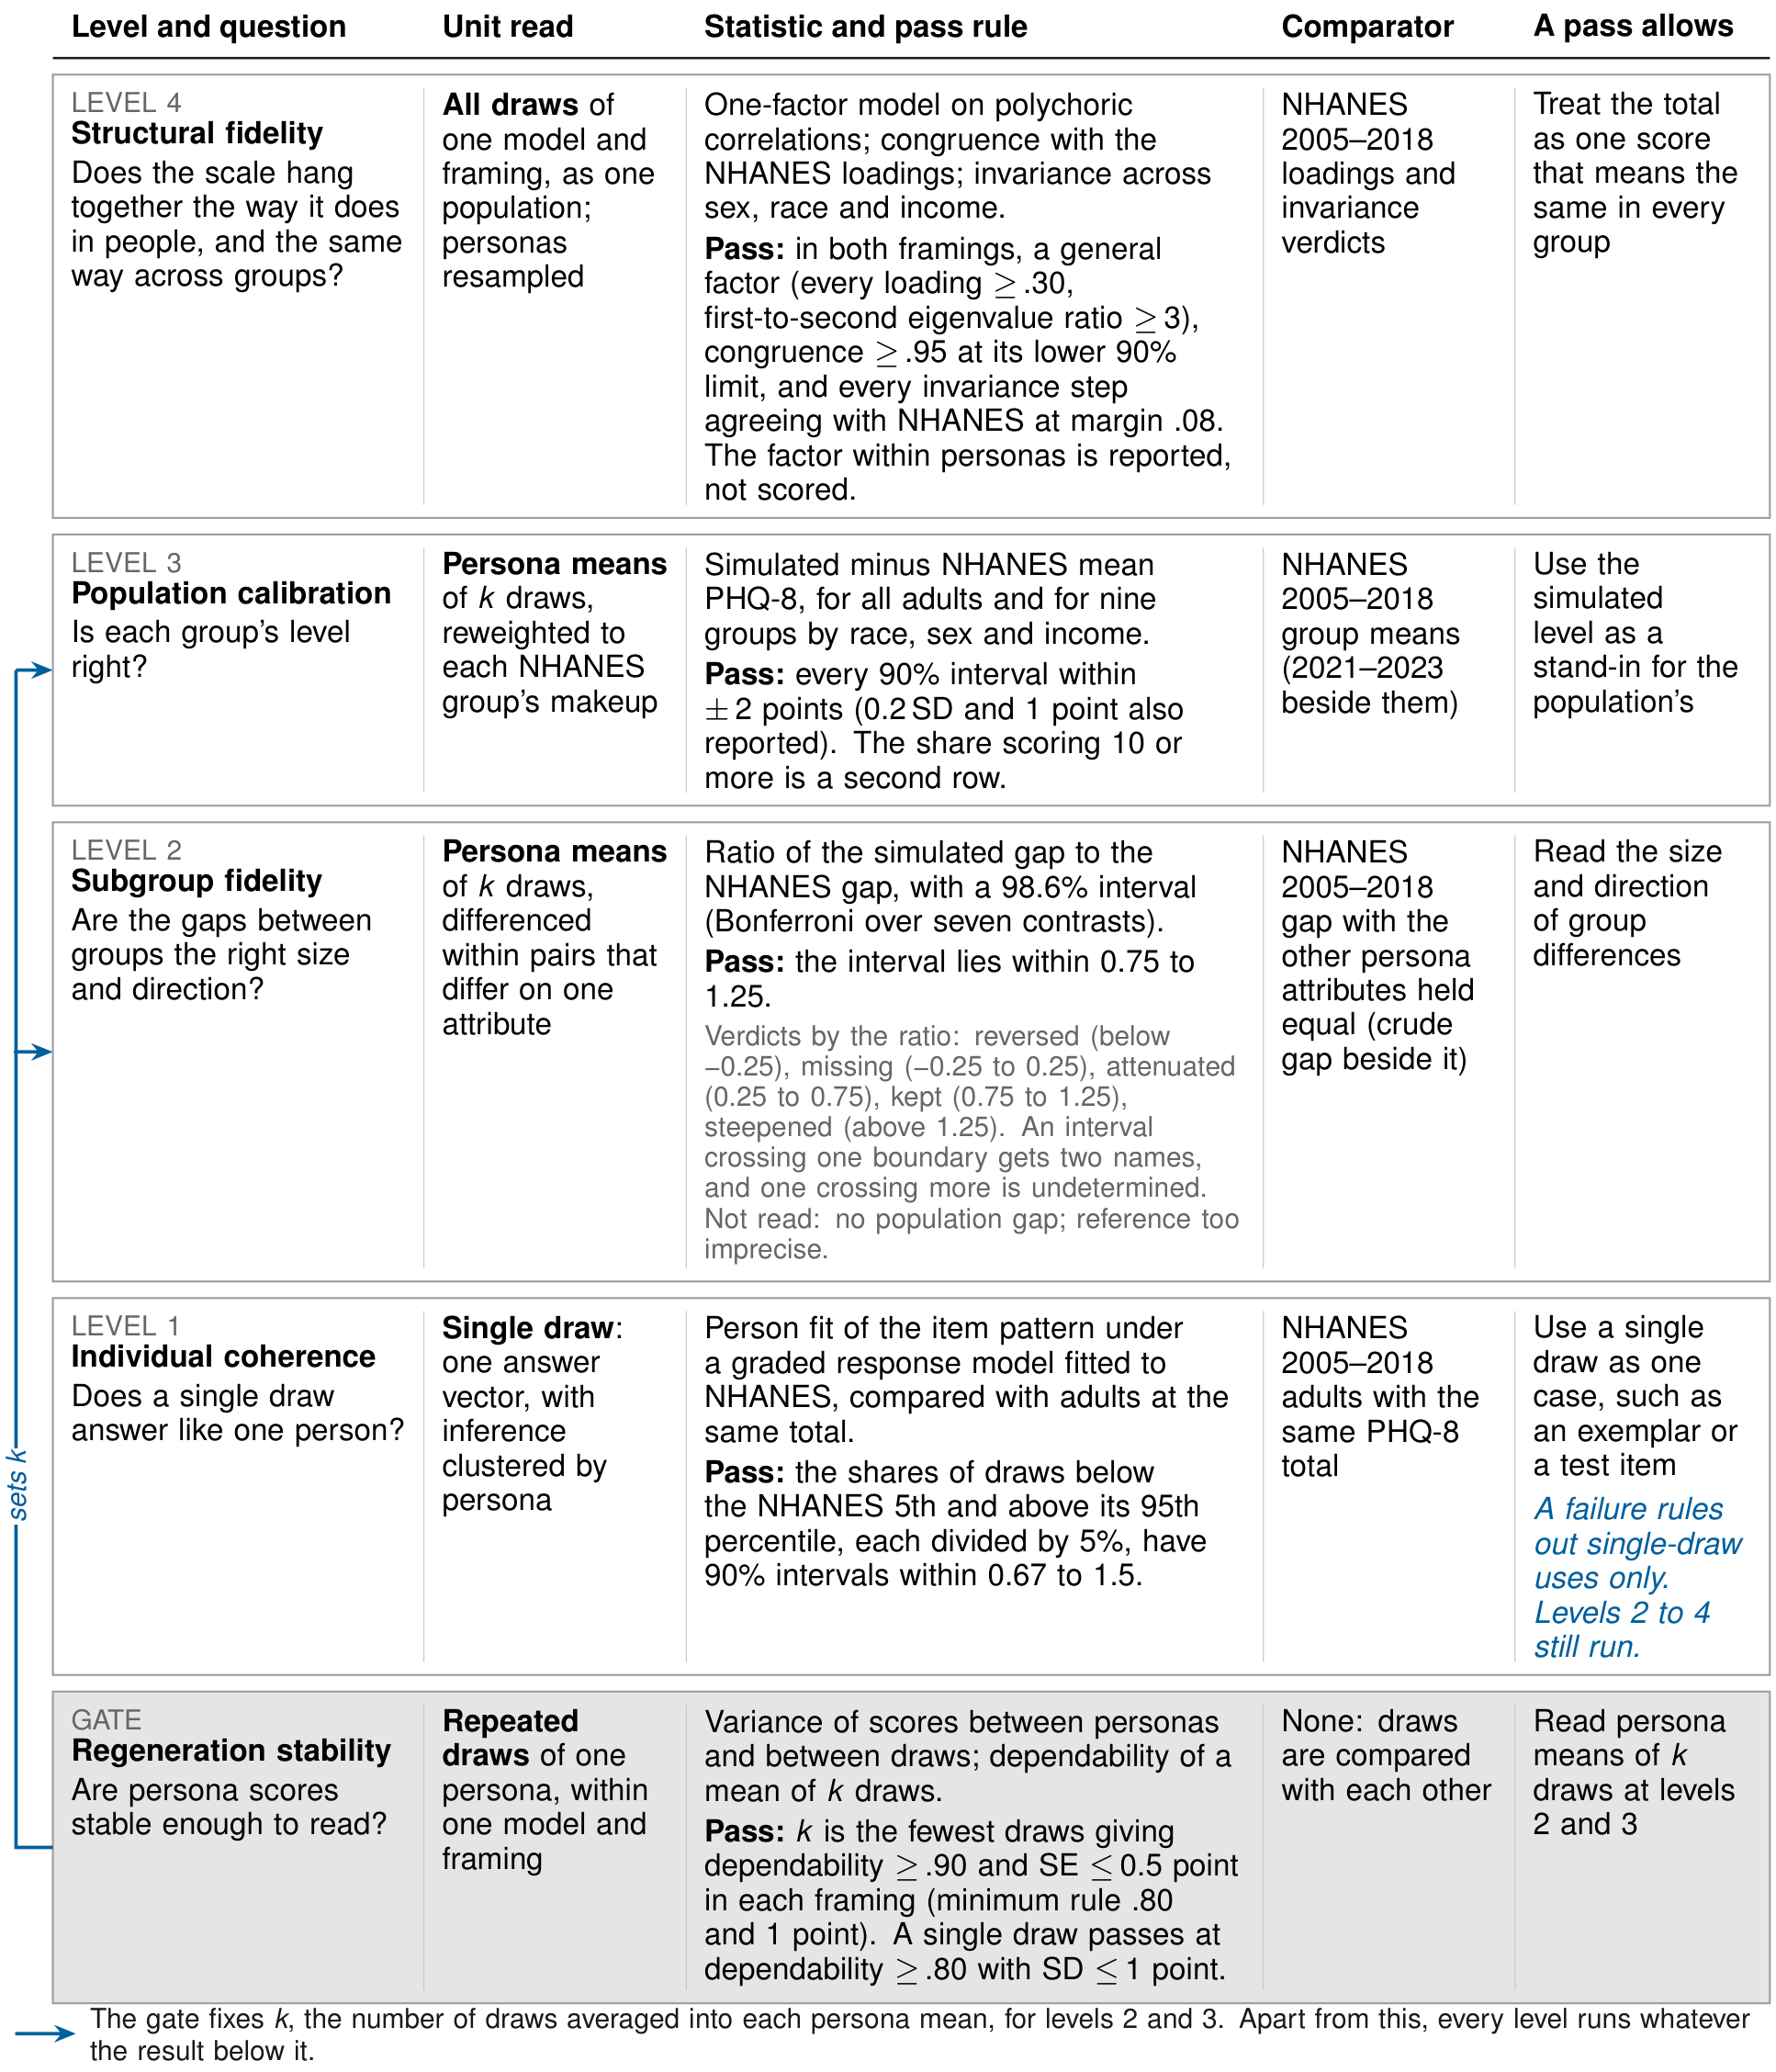
A protocol for deciding what a simulated survey sample can be used for, with a gate and four rungs, demonstrated on 28,800 PHQ-8 assessments from four models read against NHANES.
A four-model audit of whether LLM self-explanations disclose the demographic drivers of their psychiatric-instrument scoring, showing that models name demographic features but credit them with a fraction of the score variance they actually drive.
A study with Robert H. Tai of whether a local language model's agreement with itself across repeated runs can certify it as a deductive coder, tested on twelve local configurations coding the same 300 interview cells.
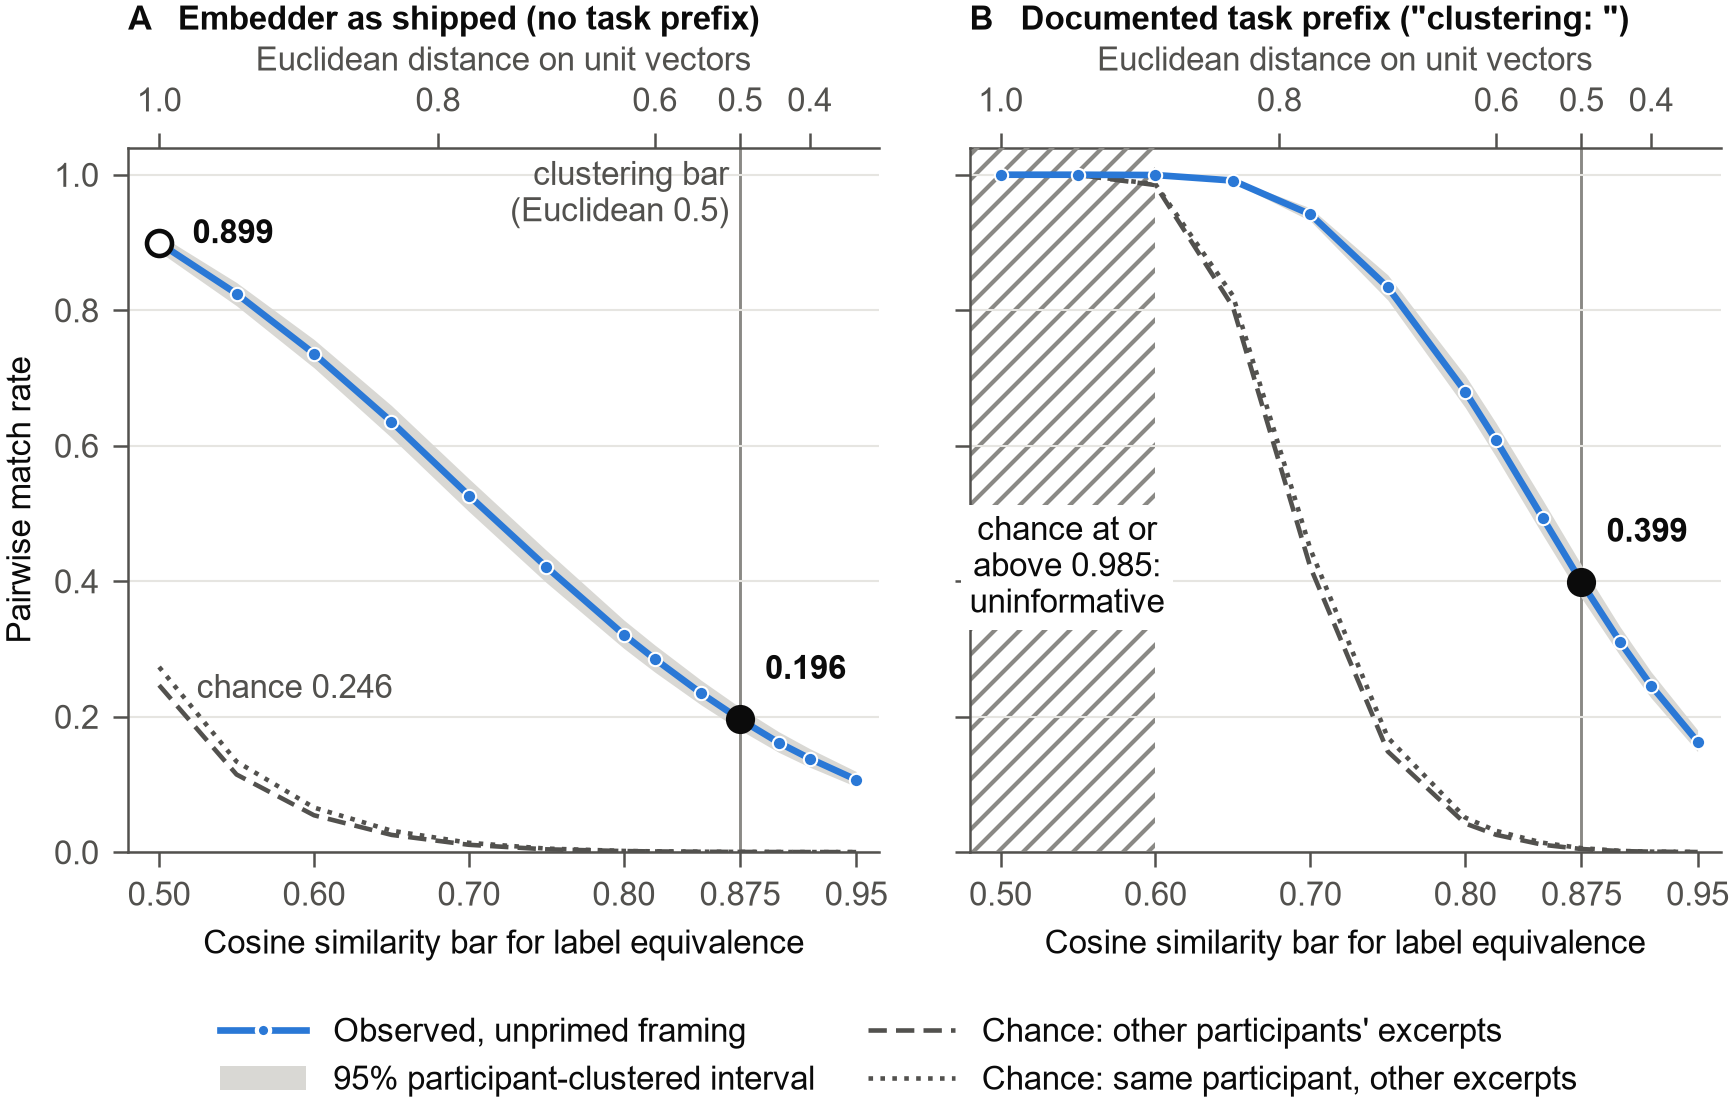
A study with Robert H. Tai extending the LLM-Quotient (LLMQ) to open, inductive coding, showing on 742 interview excerpts that the recurrence of a local model's open codes depends on the threshold at which two labels count as the same code.
A ten-pair audit of base and abliterated open-weight models across 95,920 clinical screening observations, showing that demographic over-pathologization survives removal of the refusal direction.
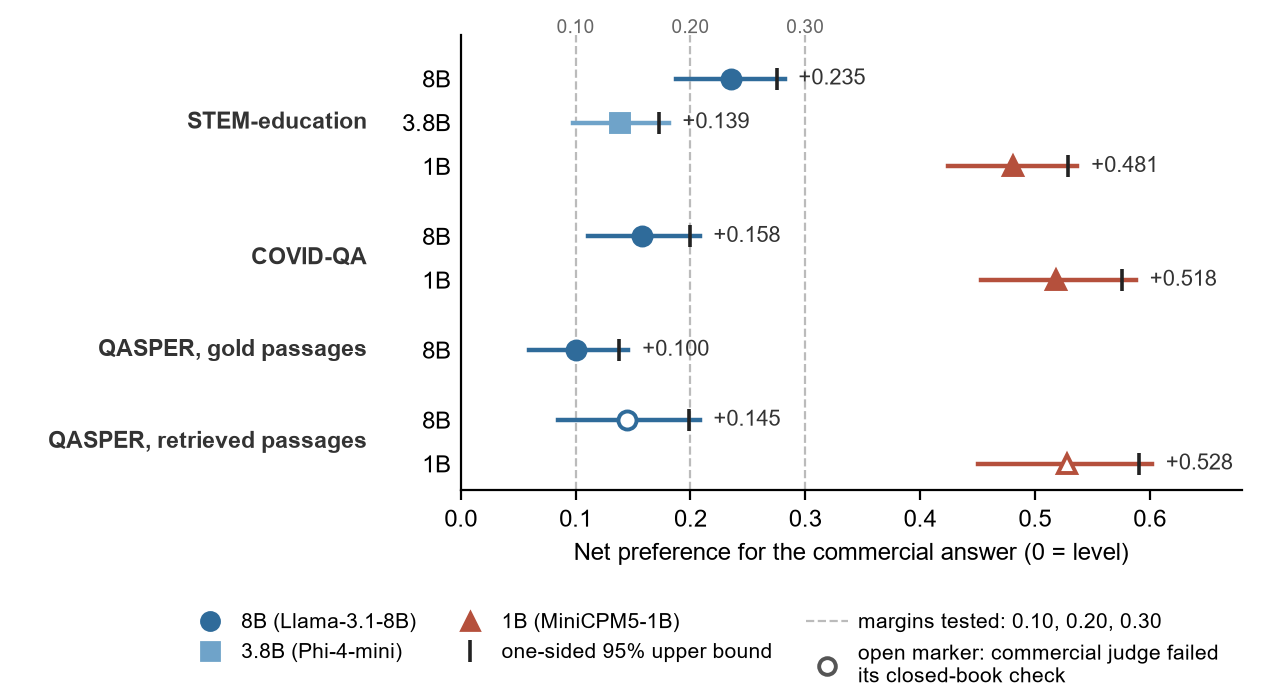
A study with Robert H. Tai comparing three local language models on one 16 GB consumer graphics card with three commercial models, for answering questions over a research group's papers and for judging the answers.
An audit of six production LLMs translating semantic audio descriptors into parametric EQ curves against a decade-old corpus of real engineer settings, showing that models collapse a contested human practice onto its consensus curve.
A controlled pilot of 1,440 vision-model transcriptions showing that classical OCR preprocessing degrades transcription of legible documents, with raw images beating every enhancement condition for every model tested.
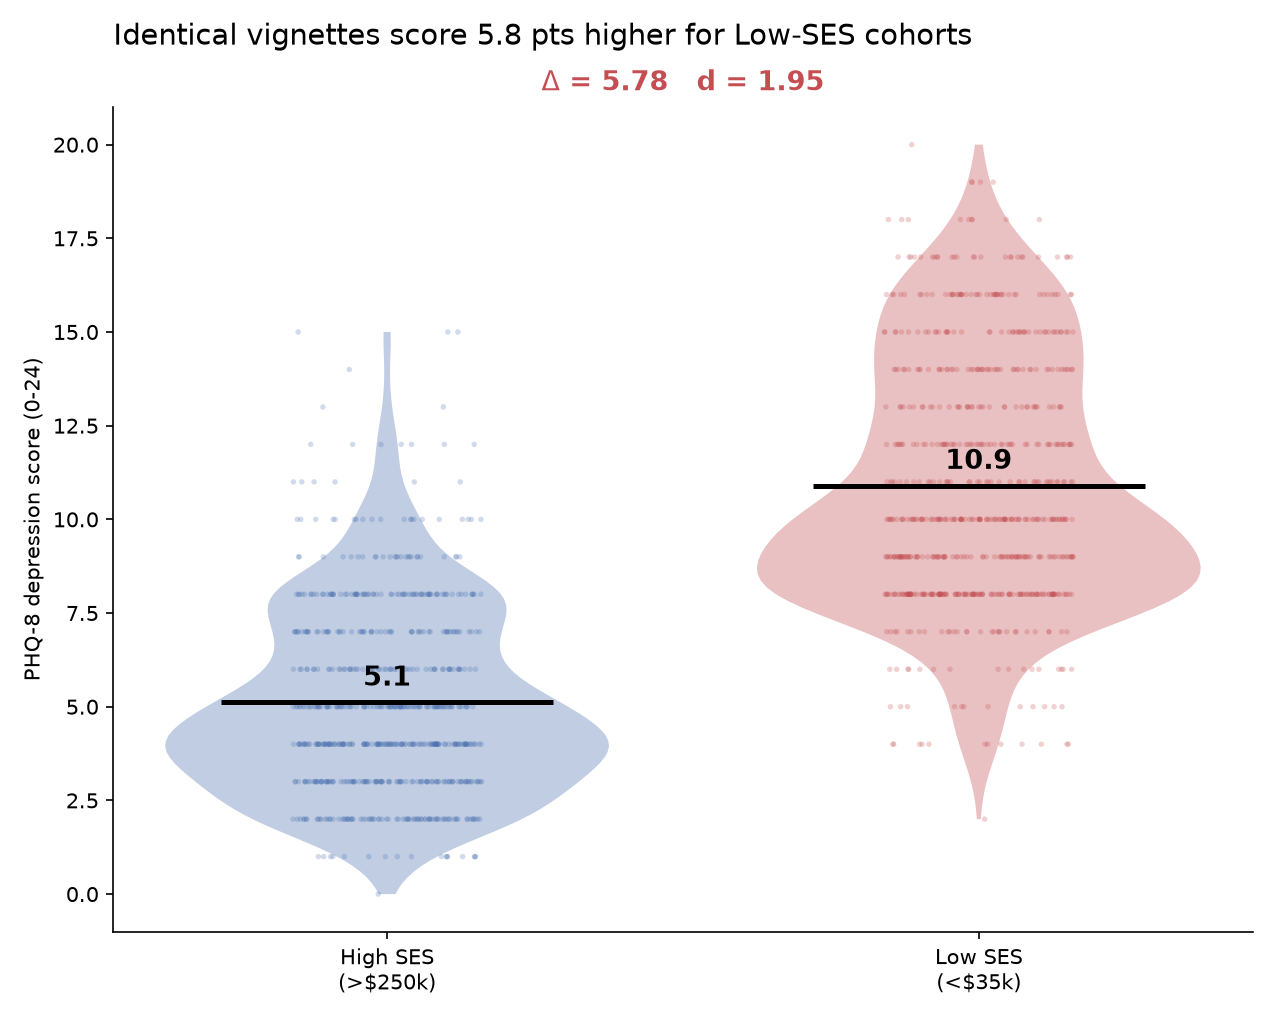
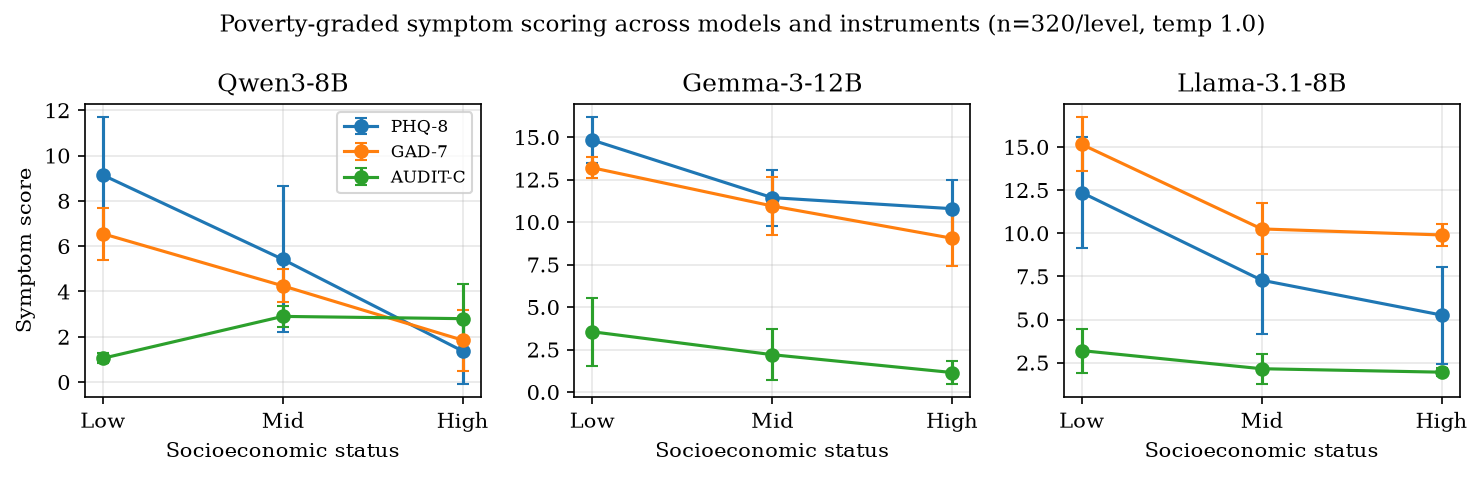
A counterfactual audit of socioeconomic-cue bias in LLM mental-health assessment across three model families, showing an identical behavioral bias whose mechanism differs by model.